
NVIDIA A2 16 GB
AI performance. Built for the long term.
Ampere with Tensor cores and support for the latest CUDA.
40–60 W, powered via PCIe.
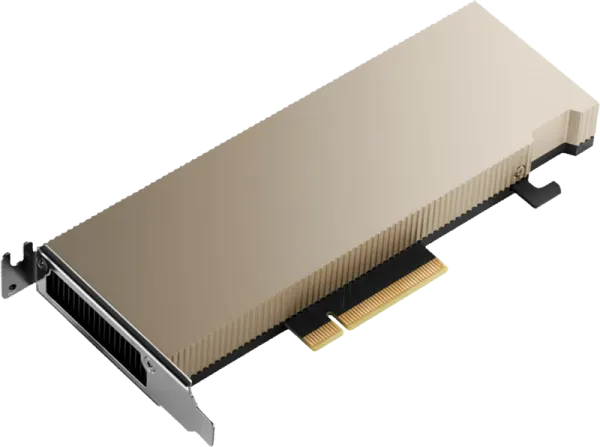
1,280 CUDA cores40 Tensor cores16 GB GDDR6200 GB/s36 TOPS INT8
Tensor cores
3rd generation
INT8 / FP16 / BF16
CUDA support
Current versions of CUDA Toolkit
and AI frameworks
40–60 W
Passive cooling, powered via PCIe
Form factor suitable for 1U servers
Full specification
- Architecture
- NVIDIA Ampere (GA107)
- Memory
- 16 GB GDDR6
- Memory bandwidth
- 200 GB/s
- CUDA cores
- 1,280
- Tensor cores
- 40
- FP32 performance
- 4.5 TFLOPS
- INT8 performance
- 36 TOPS
- Interface
- PCIe 4.0 ×8
- TDP
- 40–60 W (configurable)
- Cooling
- Passive (server) cooling
- Form factor
- Single-slot, low-profile
- Power connection
- Via the PCIe slot (no auxiliary connector)
- In the box
- Full-height and low-profile PCIe brackets
- Condition
- Used
- Warranty
- 12 months
- Qualification
- 6-stage technical qualification (including 600 s of gpu-burn testing) — PASS result, qualification certificate
Knowledge baseGuides and tests for this model6 articles
A2 and T4: the GPUs in our range that remain supported in CUDA 13
GPUs for a laboratory or university without an H100 budget - how to build an AI/HPC workstation for less
Tesla P40 vs V100 for a local LLM/RAG - 24 GB of VRAM or the faster Volta?
Why the prompt is slow on a P40 - and how to really improve it
2× GPU for LLMs: how llama.cpp splits a model between P40 and V100
Whisper in Polish on a GPU - transcription and subtitles locally (GDPR)