
Current products
NVIDIA TESLA V100 32 GB
AI performance. No compromises.
GPU accelerator for deep learning training and inference.
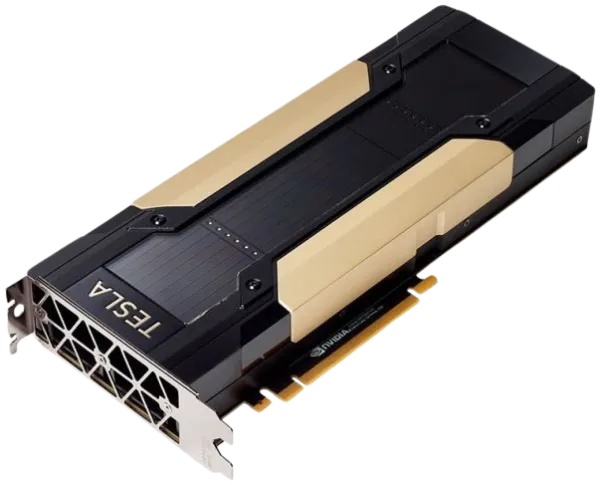
5,120 CUDA cores640 Tensor cores32 GB HBM2900 GB/s112 TFLOPS
Deep learning
AI model training
FP16 on Tensor cores
32 GB HBM2
High-speed memory
900 GB/s bandwidth
Tensor cores
112 TFLOPS of
computing performance
NVIDIA A2 16 GB
AI performance. Built for the long term.
Ampere with Tensor cores and support for the latest CUDA.
40–60 W, powered via PCIe.
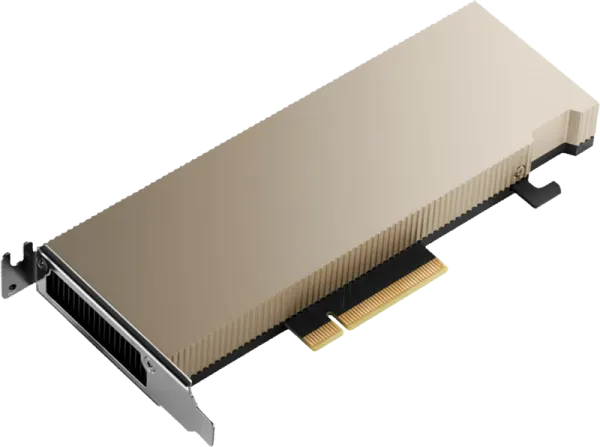
1,280 CUDA cores40 Tensor cores16 GB GDDR6200 GB/s36 TOPS INT8
Tensor cores
3rd generation
INT8 / FP16 / BF16
CUDA support
Current versions of CUDA Toolkit
and AI frameworks
40–60 W
Passive cooling, powered via PCIe
Form factor suitable for 1U servers
NVIDIA TESLA V100 16 GB
Full performance. Lower cost.
GPU accelerator for deep learning training and inference.
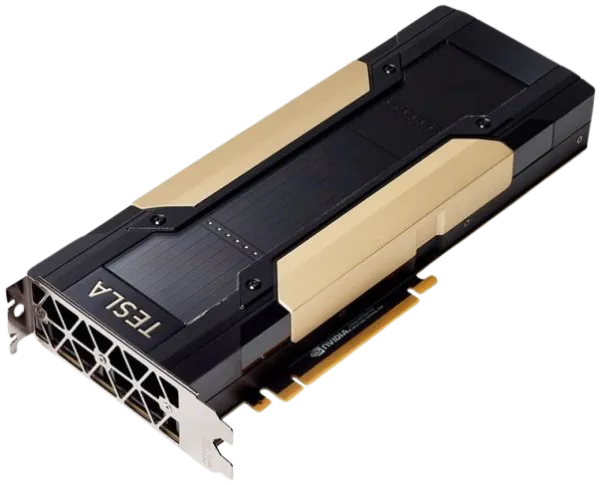
5,120 CUDA cores640 Tensor cores16 GB HBM2900 GB/s112 TFLOPS
Deep learning
AI model training
FP16 on Tensor cores
16 GB HBM2
High-speed memory
900 GB/s bandwidth
Tensor cores
112 TFLOPS of
computing performance
NVIDIA TESLA P40 24 GB
AI inference. Maximum performance.
GPU accelerator optimised for inference and virtualisation.
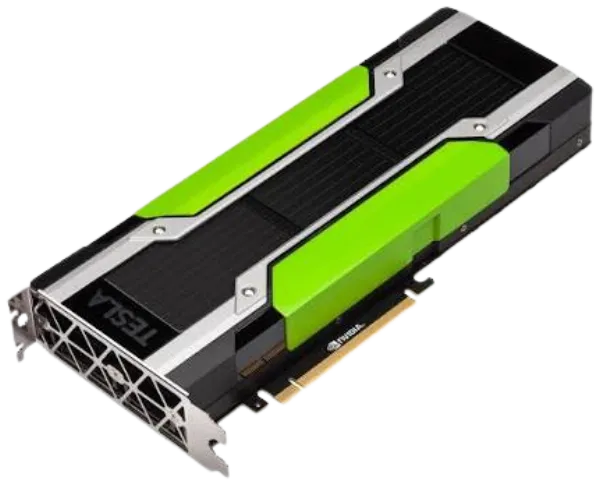
3,840 CUDA cores24 GB GDDR5346 GB/s47 TOPS INT8
Inference
Optimised for
INT8 inference
24 GB GDDR5
Large memory capacity for
complex models
Virtualisation
Support for NVIDIA GRID
and vGPU
NVIDIA TESLA P100 16 GB
HPC and deep learning.
GPU accelerator based on the Pascal architecture with HBM2 memory.
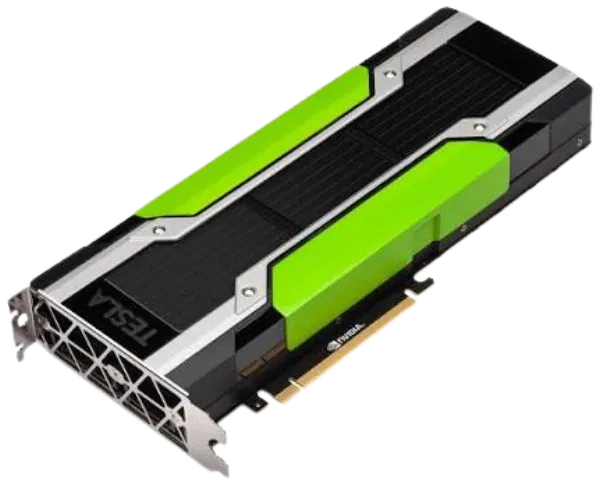
3,584 CUDA cores16 GB HBM2732 GB/s18.7 TFLOPS FP16
Deep learning
Training neural
networks
16 GB HBM2
High-speed memory
with high bandwidth
FP64 computing
4.7 TFLOPS
for HPC and simulations
NVIDIA TESLA P4 8 GB
AI inference. Low power consumption.
Compact GPU accelerator with low TDP for data-centre inference.
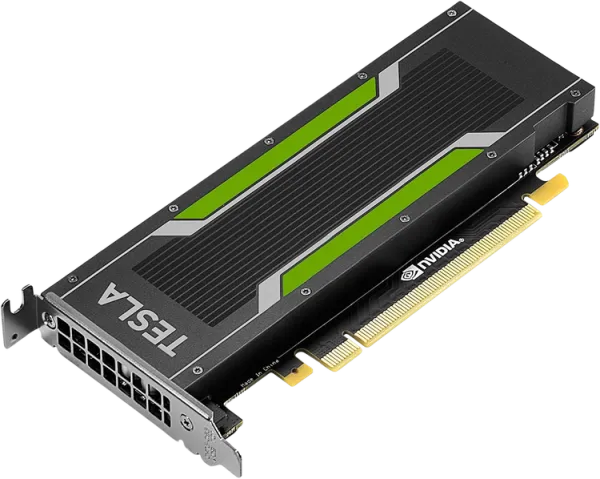
2,560 CUDA cores8 GB GDDR5192 GB/s22 TOPS INT8
Inference
Optimised for
INT8 inference
8 GB GDDR5
8 GB of
GDDR5 memory
75 W TDP
Passive cooling,
no auxiliary power required