
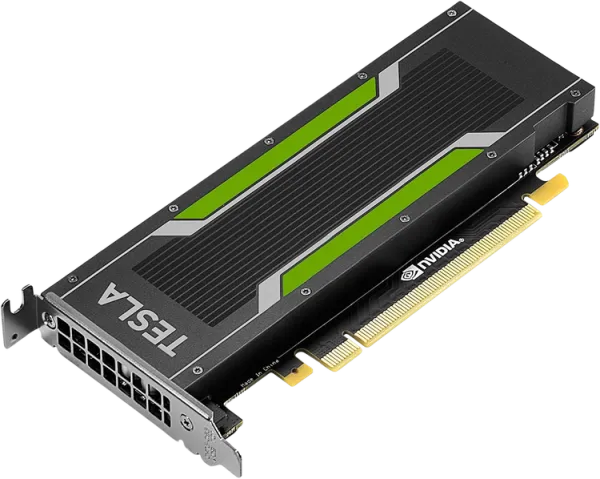
NVIDIA TESLA P4 8 GB
AI inference. Low power consumption.
Compact GPU accelerator with low TDP for data-centre inference.
2,560 CUDA cores8 GB GDDR5192 GB/s22 TOPS INT8
Inference
Optimised for
INT8 inference
8 GB GDDR5
8 GB of
GDDR5 memory
75 W TDP
Passive cooling,
no auxiliary power required
Full specification
- Architecture
- NVIDIA Pascal (GP104)
- Memory
- 8 GB GDDR5
- Memory bandwidth
- 192 GB/s
- CUDA cores
- 2,560
- FP32 performance
- 5.5 TFLOPS
- INT8 performance
- 22 TOPS
- Interface
- PCIe 3.0 ×16
- TDP
- 75 W
- Cooling
- Passive (server) cooling
- Form factor
- Single-slot, low-profile
- Power connection
- Via the PCIe slot (no auxiliary connector)
- In the box
- Full-height and low-profile PCIe brackets
- Condition
- Used
- Warranty
- 3 months
- Qualification
- 6-stage technical qualification (including 600 s of gpu-burn testing) — PASS result, qualification certificate
Knowledge baseGuides and tests for this model6 articles
Tesla P40 vs V100 for a local LLM/RAG - 24 GB of VRAM or the faster Volta?
Why the prompt is slow on a P40 - and how to really improve it
2× GPU for LLMs: how llama.cpp splits a model between P40 and V100
Whisper in Polish on a GPU - transcription and subtitles locally (GDPR)
RAG on company documents offline - what hardware and how to start (GDPR)
How much power does a used Tesla draw - and which gives the most tokens per watt